
This walkthrough shows you how to configure Provisioned Mode SQS event source mapping scaling on a real Lambda function, deploy it with SAM, push it under load, and watch the poller count climb in CloudWatch. By the end you’ll have a working ESM configured with a minimum and maximum poller count, and you’ll have seen it actually scale.
Prerequisites
Before you start, make sure you have:
- An AWS account with permissions to create Lambda functions, SQS queues, and event source mappings.
- The AWS SAM CLI installed and configured with credentials.
- The AWS CLI v2 installed and authenticated (
aws sts get-caller-identityshould return your account). - Python 3.9+ or Node.js 20.x locally if you want to run the load-test producer script.
- Basic familiarity with SQS queue attributes and Lambda event source mappings — this walkthrough assumes you know what a queue and a function are, just not how to wire Provisioned Mode scaling between them.
- Enough account-level Lambda concurrency headroom for the test — check your account’s concurrency limit with
aws lambda get-account-settingsbefore running a large load test, since a shared account limit will cap your results below the ESM’s configured maximum regardless of poller count.
One more note before you start: this tutorial intentionally keeps the poller range small (10 to 500) so the demo is cheap to run and easy to observe. The mechanics are identical at production scale — you’re just changing two numbers in the ScalingConfig block.
Steps to configure Provisioned Mode SQS event source mapping
-
Create a project directory and a minimal function handler. This is the consumer that will process SQS messages.
mkdir provisioned-esm-demo && cd provisioned-esm-demo mkdir src cat > src/app.py << 'EOF' import json def handler(event, context): for record in event["Records"]: body = json.loads(record["body"]) print(f"Processed message: {body}") return {"batchItemFailures": []} EOF -
Write the SAM template. Define the queue, the function, and the SQS event source with a
ScalingConfigblock setting min and max pollers.cat > template.yaml << 'EOF' AWSTemplateFormatVersion: '2010-09-09' Transform: AWS::Serverless-2016-10-31 Resources: DemoQueue: Type: AWS::SQS::Queue Properties: QueueName: provisioned-esm-demo-queue VisibilityTimeout: 60 ProcessorFunction: Type: AWS::Serverless::Function Properties: CodeUri: src/ Handler: app.handler Runtime: python3.12 Timeout: 15 ReservedConcurrentExecutions: 500 Events: QueueEvent: Type: SQS Properties: Queue: !GetAtt DemoQueue.Arn BatchSize: 10 FunctionResponseTypes: - ReportBatchItemFailures ScalingConfig: MinimumPollers: 10 MaximumPollers: 500 Outputs: QueueUrl: Value: !Ref DemoQueue EOFNote: this demo uses modest values (10-500 pollers) so it's cheap to run. In production you'd size
MaximumPollersup toward the new 10,000-poller ceiling based on real peak throughput. -
Build and deploy with SAM.
sam build
sam deploy --guided \
  --stack-name provisioned-esm-demo \
  --capabilities CAPABILITY_IAM
Accept the defaults for region and confirm changeset when prompted. Note the
QueueUrloutput when it finishes. -
Verify the event source mapping picked up the scaling config.
aws lambda list-event-source-mappings \
  --function-name provisioned-esm-demo-ProcessorFunction \
  --query "EventSourceMappings[0].ScalingConfig"
You should see
MinimumPollersandMaximumPollersreflecting the values from your template. -
Write a simple load-test producer. This script fires a burst of messages at the queue so you can watch the pollers scale up.
cat > producer.py << 'EOF' import boto3, json, sys, time from concurrent.futures import ThreadPoolExecutor sqs = boto3.client("sqs") queue_url = sys.argv[1] total_messages = int(sys.argv[2]) if len(sys.argv) > 2 else 50000 def send_batch(i): entries = [ {"Id": str(j), "MessageBody": json.dumps({"order_id": i * 10 + j})} for j in range(10) ] sqs.send_message_batch(QueueUrl=queue_url, Entries=entries) with ThreadPoolExecutor(max_workers=50) as pool: pool.map(send_batch, range(total_messages // 10)) print(f"Sent {total_messages} messages") EOF pip install boto3 -
Run the load test against your queue URL.
python3 producer.py https://sqs.us-east-1.amazonaws.com/123456789012/provisioned-esm-demo-queue 50000 -
Watch it scale in CloudWatch. Check the
PolledEventPollersand concurrent execution metrics for the function and queue.aws cloudwatch get-metric-statistics \ --namespace AWS/Lambda \ --metric-name ConcurrentExecutions \ --dimensions Name=FunctionName,Value=provisioned-esm-demo-ProcessorFunction \ --start-time $(date -u -d '10 minutes ago' +%Y-%m-%dT%H:%M:%S) \ --end-time $(date -u +%Y-%m-%dT%H:%M:%S) \ --period 60 \ --statistics MaximumYou can also watch it live in the Console under Lambda > Monitor > Metrics, or on the event source mapping's own detail page, which shows poller count trending upward as the queue drains.
-
Confirm the queue drains and pollers scale back down. Once the burst is processed, check the queue depth and poller count again — Provisioned Mode should hold at your minimum once traffic settles.
aws sqs get-queue-attributes \
  --queue-url https://sqs.us-east-1.amazonaws.com/123456789012/provisioned-esm-demo-queue \
  --attribute-names ApproximateNumberOfMessages
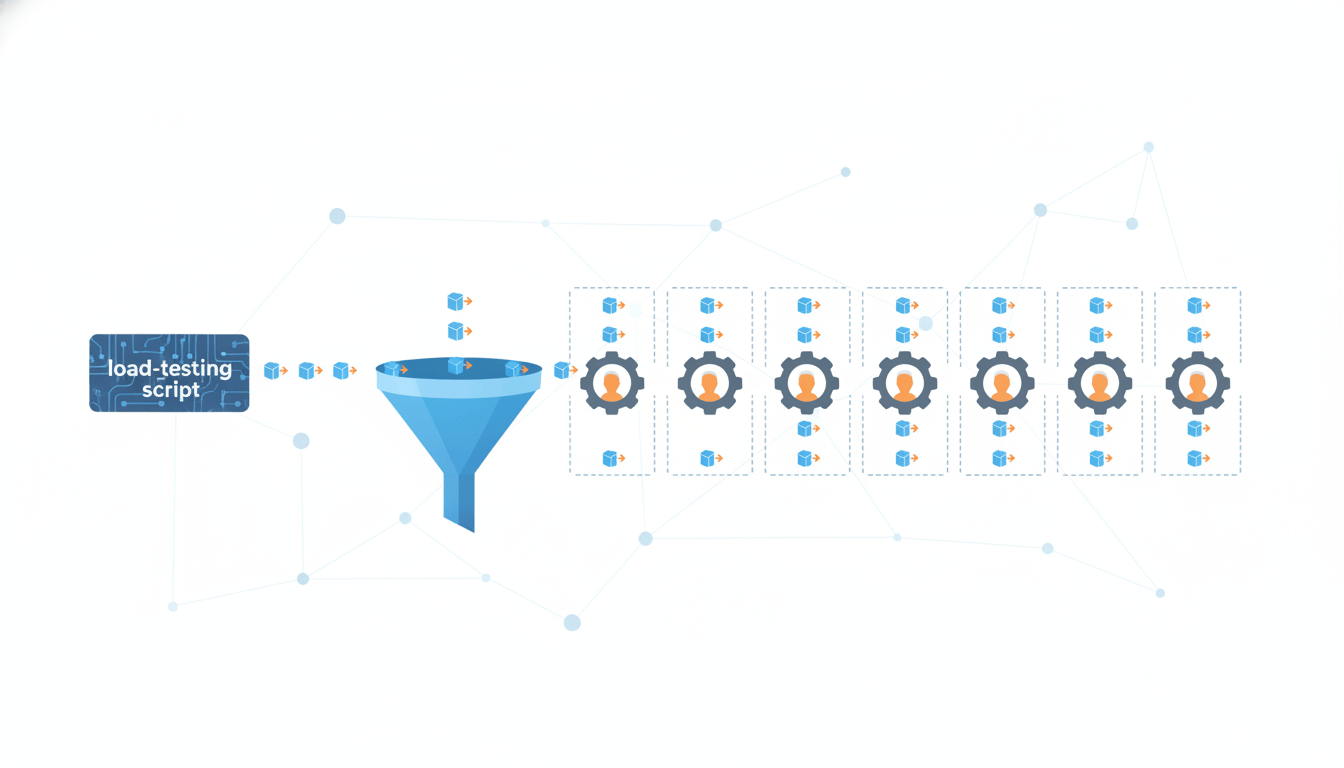
If the poller count doesn't move much during the load test, check three things in order: first, confirm the messages actually landed in the queue (ApproximateNumberOfMessages should have spiked before draining); second, confirm the function isn't erroring out on every invocation, since a function that fails immediately can make the ESM look busy without meaningfully scaling; third, confirm ReservedConcurrentExecutions on the function isn't capping invocations well below what the pollers are trying to deliver. Any of those three will produce a queue that drains slower than expected even with scaling configured correctly.
Refer to the SQS event source mapping documentation for the full set of tunable properties, and the SQS scaling behavior guide for how batch size and visibility timeout interact with poller scaling. Pricing details for Provisioned Mode are on the Lambda pricing page.
What you built
You now have a working SQS queue backed by a Lambda function with Provisioned Mode explicitly configured — a minimum poller count that keeps capacity warm, and a maximum that caps how far it can scale. You deployed it entirely through SAM, verified the scaling configuration through the CLI, pushed 50,000 messages at it with a simple concurrent producer script, and watched the poller count and concurrent execution metrics climb in CloudWatch in response. That's the same pattern you'd use to size Provisioned Mode for production order processing, transaction pipelines, or telemetry ingestion — just swap the modest 10/500 poller range for numbers that match your real peak throughput, up to the new 10,000-poller ceiling.
From here, the next steps worth taking on your own are: re-run the load test with a larger message volume and a wider poller range to see how quickly the ESM ramps toward its configured maximum, add a CloudWatch alarm on ApproximateAgeOfOldestMessage so you get paged before a backlog becomes customer-visible, and connect the consuming function to a real downstream dependency so you can validate that your database or API can actually absorb the concurrency you just proved Lambda can deliver. The scaling configuration is the easy part — the discipline is making sure everything downstream of it can keep up.
At Enkompass (enkompass.net), this is our home turf. We build and load-test event-driven pipelines like this one for clients before their traffic spike finds the weak spot first. If you'd rather have seasoned cloud people handle it instead of learning the hard way at 2 AM, let's talk. Reach out through our contact page or call us directly at +1-828-436-5667 — we'll help you turn this from a someday-project into a done-deal.